(09/10) Our own product, 2026
Pitch Daily
Public data in, investment memos out, unattended.
(01) Overview
Public data in, investment memos out, unattended. A research system that runs itself, for less than a penny a cycle.
(02)
The challenge
Most “AI does your research” tools are one API call in a nice wrapper. They work in a demo and fall over in production, because real data sources go down, rate-limit, change their pages or return nothing at all.
The hard part was never the writing. It was building something that keeps running when a source disappears, and that doesn’t quietly run up a bill while nobody is watching.
(03)
What we did
-
01
Automation
A scheduled pipeline that runs unattended and recovers from failures on its own.
-
02
Data pipeline
Fourteen public sources, taken in, cleaned up and scored against one rubric.
-
03
AI integration
Write-ups from a language model, with a hard spend cap and a rule-based fallback.
-
04
Dashboard
One operator view for candidates, case files and the track record.
(04)
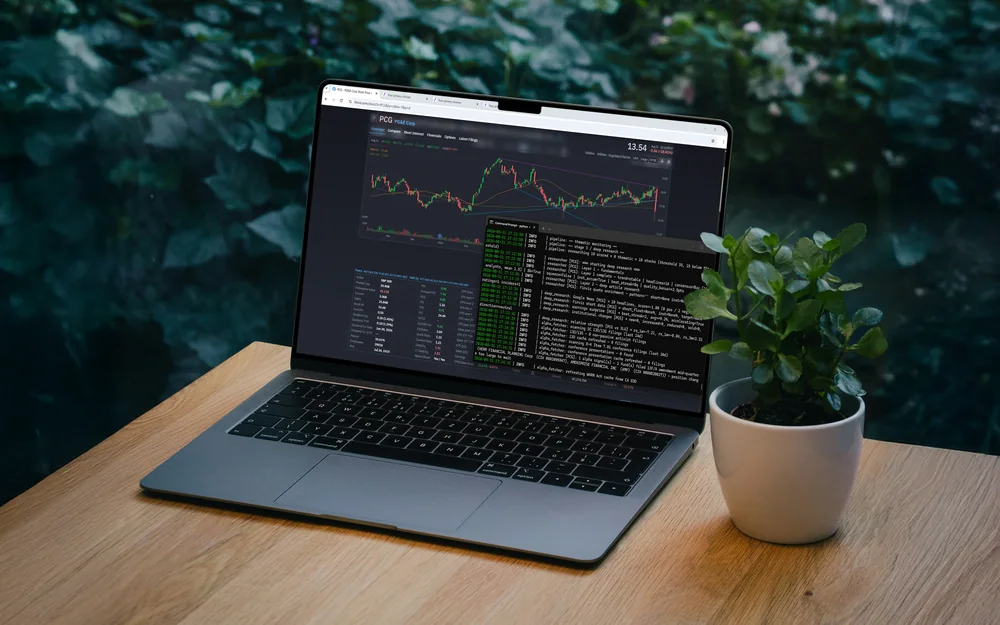
One cycle
- 04:00:02cycle start
- 04:00:03discovery finviz62 candidates
- 04:00:09discovery sec edgar41 filings
- 04:00:14discovery openinsider18 transactions
- 04:00:19discovery finra reg shook
- 04:00:24discovery news rss113 items
- 04:00:26discovery congress tradesok
- 04:00:31discovery fred macrono data, skipped
- 04:00:32repair fred adapterqueued, next cycle
- 04:00:33score weighted rubric25 ranked
- 04:00:44research top 9dossiers built
- 04:01:12write gpt-4o-mini9 memos
- 04:01:12spend $0.008under cap
- 04:01:13cycle completenext run 04:30
(05)
The approach
Discovery pulls from fourteen public sources, including SEC filings, insider transactions, short-interest data and news. A source that fails is skipped rather than stopping the run, and its adapter is repaired for the next cycle. Candidates are scored against a weighted rubric, and only the best few each cycle get the expensive treatment.
The write-up uses a language model with a hard daily spend cap. When the cap is hit it falls back to rule-based summaries instead of stopping. That fallback isn’t a failure state, it’s the design: the system keeps producing on a bad day instead of going quiet.
It runs every thirty minutes on a small server, unattended, for a fraction of a penny a cycle.
Built with
- A small cloud serverRunning the loop around the clock, every thirty minutes.
- GPT-4o miniThe write-ups, under a hard daily spend cap.
(06)
What we built
-
01
A scheduled research loop
Discovery, scoring, research and write-up, every thirty minutes.
-
02
It fails soft
A failing source is skipped, not fatal, and the adapter is repaired for the next cycle.
-
03
Cost control
A hard daily spend cap with a rule-based fallback, so it keeps producing and never runs up a bill.
-
04
An operator dashboard
Candidates, case files and track record in one place.
(07)
How it runs
-
$0.008
Per research cycle
-
14
Public data sources
-
30 min
Unattended, on a schedule
Want something like this? Tell us what you need. You’ll get a fixed price and a date within 24 to 48 hours.
Start your project